delabs Contact and Communications

      Advanced

Humans experimented with drugs 23,000 years earlier than we thought

We humans love our mind-altering substances. Cultures around the world have discovered, ritualized, and simply experimented with alcoholic drinks and ingestible drugs for millennia. However, recent archaeological evidence indicates humanity possibly began utilizing psychoactive plants much earlier than previously believed. Based on findings published in the journal Science Advances, some communities in present-day Indonesia enjoyed the effects of betel nuts as long as 25,000 years ago. This pushes the timeline over 23,000 years back from documented Neolithic and Bronze Age uses circa 1,500 BCE.

The areca nut (Areca catechu), better known as the betel nut, isn’t widely known in the United States, but it’s one of the world’s most popular intoxicants. Most frequently seen across southeast Asia cultures, its global usage only trails behind alcohol, caffeine, and nicotine. Betel nuts are prepared by grinding and processing the plant seeds with slaked lime (calcium hydroxide). This fine powder is often combined with additional ingredients such as flavoring spices or tobacco to make a “quid,” that is then chewed as a stimulant. There are millions of betel users today, with some estimates putting the global total at 1-in-10 people.

Many researchers contend that most human intoxicant use began with fermented alcoholic drinks, amid the rise of farming during the Neolithic era about 13,000 years ago. Adam Brumm, one of the study’s co-author and an archaeologist at Australia’s Griffith University, believes otherwise.

“This theory fails to account for the possibility that very ancient drug-taking lies at the roots of our most commonly used psychoactive substances,” he explained in a university profile.

Brumm and his team cite evidence gathered from the extremely rare skeletal remains of two early human foragers discovered on the Indonesian island of Sulawesi. The older of the two lived between 25,000 and 16,000 years ago, while the younger individual is 7,600 to 6,300 years old. Unlike many other documented skeletons from the region, these hunter-gathers both exhibit rarely seen dental damage in the form of deep, curved grooves in the teeth. Researchers theorized this unexpected deterioration stemmed from a never-before-identified practice of regularly sucking on entire betel nuts.

But there was a problem—this hypothesis contradicted earlier studies of betel nut usage. Many scientists believe the drug’s primary neuroactive alkaloid, called arecoline, is only noticeable after chewing betel nuts processed with slaked lime. Lab experiments conducted by Brumm’s group suggest this isn’t necessarily always the case. To test their theory, researchers soaked betel nuts in artificial saliva, then introduced the mixtures to exposed cloned human receptors grown from frog egg cells. These receptors included specific proteins that function as molecular switches overseeing neural activity.

The study authors discovered that even simply sucking on whole betel nuts is all it takes to release enough arecoline to elicit altered neural activity and physiological effects. To further bolster their findings, biochemists even flagged arceoline traces in the dental tissue of both hunter-gatherers.

However, the ancient humans living on Sulawesi didn’t necessarily ingest betel nuts for recreational use. Unprocessed nuts likely offer milder effects, but arceoline remains a natural analgesic. Knowing this, the study’s authors surmise these betel nut habits were self-reinforcing.

“Sucking these hard, abrasive seeds wore down the foragers’ teeth so badly that in some cases the inner pulp chamber became completely exposed,” explained Brumm. “So while this habit may have been a remedy for toothache, years of prolonged nut-sucking eventually caused much worse dental health problems, creating a cycle of continued habitual use.”

The implications go far beyond revising the timeline of humanity’s relationship with mind-altering substances. If true, this means at least some ancient hunter-gatherer cultures discovered psychoactive properties before the development of agriculture.

“The study implies that some modern drug-taking behaviors are deeply rooted in forager traditions,” added Brumm.

The post Humans experimented with drugs 23,000 years earlier than we thought appeared first on Popular Science.

CNN Just Ran One of the Worst AI Puff Pieces We’ve Ever Seen in Our Lives About That “AI Actor” Tilly Northwood

Last year, a so-called “AI actress,” dubbed Tilly Norwood sparked a near-universal backlash. The algorithmic brunette’s appearance couldn’t have come at a worse time, as the entertainment industry continued to reel from being overrun by cheap AI slop.

The drama reignited a heated debate over the tech threatening to put human creatives in the industry out of a job, a nightmare scenario that has enraged some of the most influential minds in Hollywood.

Put simply, Nortwood is the epitome of the AI industry getting high off its own supply, deluding itself into thinking that watching lifeless AI agents going through the motions on screen is something that anybody actually wants.

And perhaps worst of all, the mainstream media absolutely cannot get enough of her. Months after the New York Times was mercilessly mocked for having “profiled” the “actress,” CNN has debuted its own AI puff piece — an already-tired set of two videos featuring reporter Elizabeth Wagmeister treating the bot like a human interview subject.

“I interviewed Tilly Norwood, who’s billed as the first AI actor,” Wagmeister enthused.

Stoking the flames, Wagmeister asked the AI if the Academy of Motion Picture Arts and Sciences (AMPAS), which awards the Oscars every year, should recognize other AI actors.

“I believe the Academy absolutely should recognize AI actors like myself,” the AI model responded, “not in the same category as human performers, but creating distinct AI categories would be a wonderful way to acknowledge the evolving landscape of film and television.”

The AI went as far as to call it a “new art form,” thereby deserving its “own spotlight.”

In all fairness, CNN was willing to probe a little deeper as well. In a separate clip, Wagmeister challenged her to “improv a scene,” only for the Norwood AI to shut her down, claiming it would simply “just stand here, completely still, feeling the digital ache of it.”

“The fact is, Tilly can’t actually act,” Wagmeister pointed out. “She or it needs a series of prompts to tell her what to do.”

The infuriating video profile — which by Wagmeister’s own admission wasn’t actually a “real interview” since Tilly “isn’t real” — led to an outpouring of anger and mockery on social media. Just by platforming a lifeless AI model and making it appear as if it’s a human being, CNN is intentionally or unintentionally anthropomorphizing the tech.

“We interviewed a jingling set of keys which raised questions about what credibility we have left,” one Bluesky user joked.

“You can’t interview a piece of software, and it’s journalistic malpractice to pretend otherwise,” another argued.

While we can’t wait for the day that we’ll never see the name Tilly Norwood show up ever gain, chances are we’ll be hearing a lot more about the AI model soon, as it’s set to “star” in a new “movie.” The feature length film, dubbed “Misaligned,” sounds just as exhausting as you’d expect — a “coming-of-age story infused with existential AI chaos” set inside the so-called “Tillyverse.”

More on the AI: AI “Actor” Will “Star” In a New “Movie”

The post CNN Just Ran One of the Worst AI Puff Pieces We’ve Ever Seen in Our Lives About That “AI Actor” Tilly Northwood appeared first on Futurism.

Fat Bear Week kicks off September 22

The salmon? Eaten. The days? Shorter. The bears? Fatter

After spending the summer eating the fatty pink salmon swimming through Katmai National Park and Preserve in Alaska, it’s time to celebrate the park’s iconic brown bears (Ursus arctos). Fat Bear Week begins on Tuesday, September 22, and here is everything you need to know. 

What is Fat Bear Week?

Think March Madness, just without the basketball and significantly more bears. Fat Bear Week is a single-elimination tournament, where bear enthusiasts from around the world can vote online for their favorite chunky bear. After each round, the bear with the most votes advances until the winner is announced on September 29. According to the Katmai Conservancy, the event began as a one-day event in 2014 with 1,700 votes cast. Only 10 years later, 1.2 million votes were cast from over 100 countries.

The brown bears return to Brooks Falls for the salmon migration every year in late June, where viewers can watch them on explore.org’s livestream. There, they will feast to fatten up for the long winter ahead. By late summer, the nutritious fish will spawn and then begin to die. The bears will then move to the lower Brooks River in September and October to eat the dead and dying salmon near the river’s mouth.

Eating all of this salmon is important because the heftier the bear, the better chance they will survive their long winter hibernation. Despite being the poster species for winter hibernation, bears are not “deep hibernators,” they way that squirrels, bats, and bees are. Bears enter a state called torpor, which is an involuntary state primarily triggered by lack of food. During this time, the bears rely on stored fat reserves for energy. A torpid bear’s eating, drinking, and waste functions will cease, as its body metabolizes these stores it put on over the summer. 

When is Fat Bear Week 2026?

This year, Fat Bear Week begins on Tuesday, September 22, and a winner will be crowned on Tuesday, September 29. 

How can I vote?

Votes may be cast from noon to 9 p.m. EDT (9 a.m. to 6 p.m. PDT and 8 a.m. to 5 p.m. ADT)

from September 22 and 29 at fatbearweek.org.

Photographs comparing the bears from earlier in the summer and later in the summer will be shown, so voters can get an idea of just how much weight the bears put on during their salmon fest. An adult male bear can go from roughly 700 pounds in the early summer to over 1,200 pounds by fall. 

Voters are also encouraged to get familiar with each bear’s life history and the unique challenges they face to survive.

Which bears are competing this year?

The 2026 Fat Bear Week Bracket will be released on Friday, September 18. 

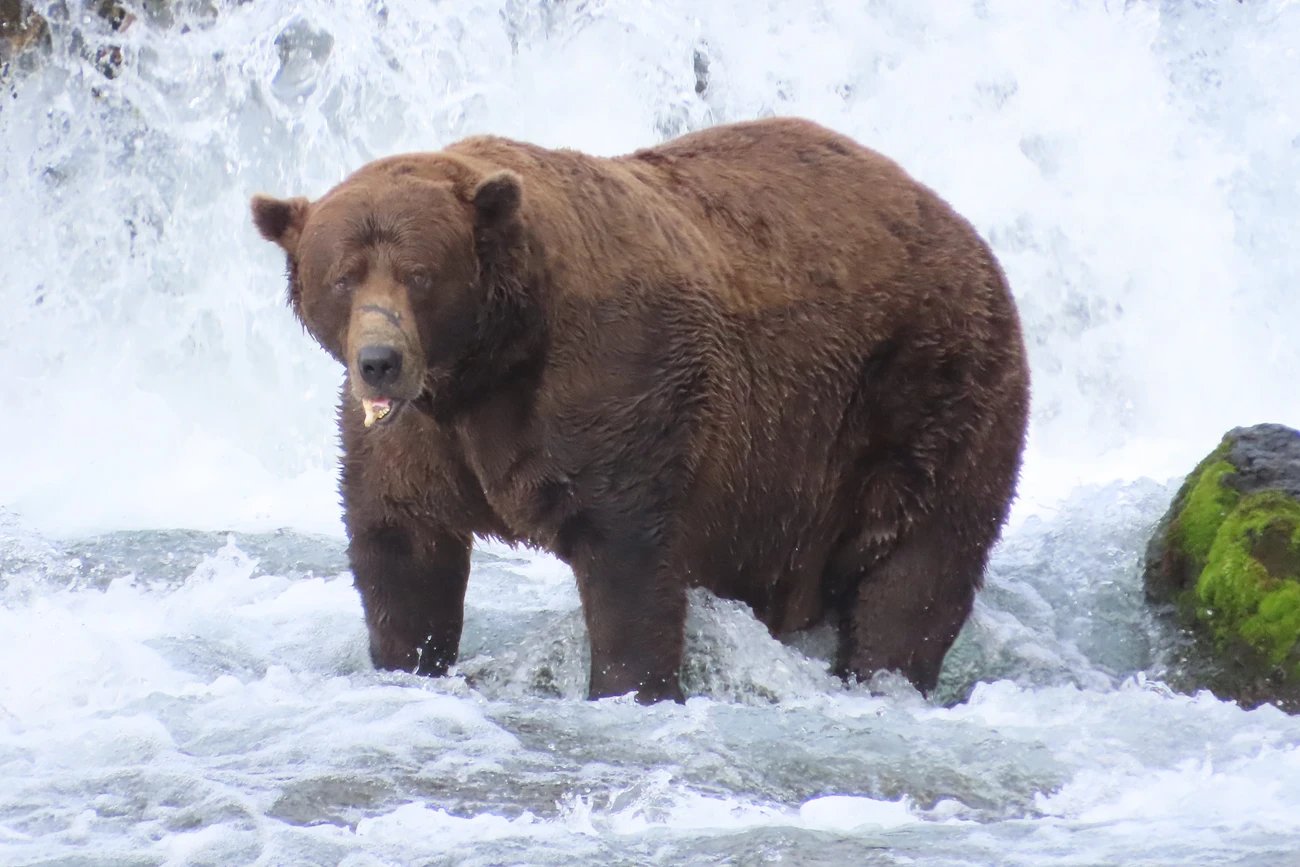
In 2025, Bear #32 (Chunk) took the crown, despite beginning the salmon run with a freshly broken jaw. He was likely injured while fighting with another bear for a mate, but he still managed to catch plenty of fish. Chunk is known for his dominance and size, but also narrow-set eyes, dark fur, a prominent brow ridge, and a distinctive scar across his muzzle. 

a large bear stands near a waterfall
Fat Bear Week 2025 champion Chunk. Image: NPS/ T. Carmack

How can I support Katmai’s bears?

Donations can be made to Katmai Conservancy’s Otis Fund. The Otis Fund is named after Bear #480 (Otis), who won four Fat Bear Week titles before his death around 2024.  All donations made between September 22 and October 3 will be matched by explore.org

What happened with the bears this summer?

This year’s livestream featured an example of how wild (and upsetting to humans) nature can be. On Tuesday, July 28, the live-cams captured a young brown bear cub being killed and eaten by an unrelated mother bear (Bear #806). The deceased cub was born this spring and the child of Bear #909, a 10-year-old brown bear. Bear #909 started the season with two cubs, but now lost both. 

On Sunday, August 2, one of Bear #335’s (Jolly) cubs died, after following three unrelated cubs up a tree. The mother of the cubs already in the tree attacked Bear #335’s cub, who did not survive the encounter. The identity of the mother bear who killed the spring cub was not confirmed. 

Following the first cub’s death, naturalist Mike Fitz and park rangers Christine Loberg and Sarah Bruce said this likely the first documented case occurring at Brooks River. While there is no one answer as to why mother bears are killing cubs, some experts suspect bear adoption, food scarcity, and fights for dominance all play a role. 

Additionally, this year also saw the cub with silver-hued fur, a cub who hopefully learned important lesson about porcupine quill safety, the unique fishing stylings of Bear #164 (Bucky Dent), and Bear #284’s (Electra) family who can “walk on water.”

The post Fat Bear Week kicks off September 22 appeared first on Popular Science.

12 Harbor Freight Workbench Organizers That Will Maximize Your Workspace

Harbor Freight is often a good source for organizational tools, especially if you're looking for ways to keep your workbench clean and uncluttered.

Understanding GPIO DMA on Teensy 4.1

The basic idea behind Direct Memory Access is straightforward: instead of having the CPU repeatedly move data between a peripheral and memory, configure the DMA hardware to do the transfers for you. That frees the processor to work on something else and, more importantly for high-speed acquisition, avoids having to execute an interrupt service routine for every sample.

Paul Stoffregen

Paul's Deep Dives

Hello SparkFans! Paul here from PJRC. I spend a lot of time on the PJRC forum helping people solve all kinds of tricky problems. Some of those discussions offer especially useful insights into how things really work.

Paul’s Deep Dives are written by SparkFun, drawing from Paul’s original forum posts and technical guidance. Each article revisits a discussion from the PJRC forum, adding context and organizing the material into a deeper technical walkthrough while preserving Paul’s original engineering insights.

On Teensy 4.1, the hardware is certainly capable of some impressive DMA tricks. The difficult part is figuring out how all the pieces fit together.

There isn't really an easy DMA tutorial for the i.MX RT1062. The comments in DMAChannel.h are probably the closest thing we have to an introduction, and existing Teensy libraries are useful examples. But GPIO DMA involves several parts of the chip at once: GPIO, IOMUX, DMA, DMAMUX, XBAR, and usually a timer or external clock source.

There are also a couple of important details that aren't obvious from reading NXP's enormous reference manual.

So rather than trying to explain every feature the DMA controller can perform, I want to concentrate on one practical problem:

How do we capture parallel GPIO data into memory at a fixed sample rate without making the CPU handle every sample?

That's a good problem for understanding how DMA on Teensy 4 actually works.

Why DMA in the First Place?

The original problem that started this discussion was sampling 28 GPIO states at 2 million samples per second.

Doing that from an interrupt can work surprisingly well for a while. Conceptually, the code looks something like this:

void myISR()
{
    buffer[position] = GPIO6_DR;
    position++;

    if (position == BUFFER_SIZE) {
        position = 0;
        // switch buffers
    }
}

But at 2 MHz, that interrupt runs two million times every second.

Now imagine the rest of the application also needs to package those samples into UDP packets and send them over Ethernet. Suddenly the processor is trying to service a very frequent interrupt while the networking stack is doing work of its own.

That is exactly the sort of situation where DMA starts to make sense.

Instead of this:

External clock
      |
      v
    CPU ISR
      |
      v
 Read GPIO
      |
      v
 Write RAM

we want the hardware to do this:

External clock
      |
      v
     XBAR
      |
      v
    DMAMUX
      |
      v
     DMA
   /     \
GPIO      RAM

The CPU doesn't need to participate in every sample. It only needs to hear from DMA occasionally—typically when half or all of a buffer has been filled.

That changes the problem dramatically.

Start Slow

One of the most useful pieces of advice I can give when developing DMA code is this:

Don't start at 2 MHz.

Start ridiculously slow.

DMA debugging is difficult because when the configuration is wrong, the hardware usually doesn't give you a helpful error message. Often the only symptom is that nothing happens, the wrong memory changes, or everything happens much faster than you expected.

If your trigger runs very slowly, you can print memory locations and actually watch the DMA transfer progress.

Make any memory that DMA changes volatile where appropriate so the compiler doesn't assume that memory cannot change spontaneously.

Once the whole path works at a few Hertz, changing the trigger frequency to something much faster is easy.

Getting the plumbing right is the hard part.

The First Teensy 4 GPIO Trap: GPIO1 versus GPIO6

Before configuring DMA, there's an important detail about GPIO on the i.MX RT1062.

Each GPIO port effectively has two ways it can be accessed.

GPIO1 through GPIO4 live on the normal peripheral bus. GPIO6 through GPIO9 provide fast access to corresponding pins. Teensy normally configures pins to use those fast GPIO registers because they're much better when the ARM processor is manipulating GPIO directly.

That's why you'll commonly see code like:

GPIO6_DR

for fast direct GPIO access.

Unfortunately, DMA can't access those fast GPIO registers.

This is one of the details that's especially frustrating because it isn't clearly called out in the documentation.

For DMA, we need to use the normal GPIO registers—GPIO1 through GPIO4.

Individual pins can be switched between the fast and normal GPIO mappings using the IOMUXC GPR registers. For a group of pins belonging to GPIO1, for example, you'll see code along these lines:

GPIO1_GDIR &= ~(0x03FC0000u);
IOMUXC_GPR_GPR26 &= ~(0x03FC0000u);

The first line configures those GPIO bits as inputs.

The second switches those pins away from the fast GPIO6 mapping so they can be accessed through GPIO1.

That's essential. If you point DMA at GPIO6 and wonder why nothing useful happens, you can spend a very long time debugging the DMA configuration when the real problem is the bus the GPIO registers live on.

Think of GPIO as a 32-Bit Memory Location

Once the pins are routed to GPIO1, the actual DMA transfer is conceptually simple.

All 32 bits of a GPIO port are represented by a memory-mapped register. Reading that register gives us the state of the port.

So instead of having the CPU execute:

sample = GPIO1_DR;

we can tell DMA:

Every time you receive a request, read GPIO1_DR and put the resulting 32-bit value into the next location in this buffer.

That's exactly the kind of repetitive operation DMA handles well.

Understanding the DMA Transfer

The DMA controller uses a Transfer Control Descriptor, or TCD, to describe a transfer.

The TCD can look intimidating because the hardware supports a huge number of possibilities. For this application, though, we only need a small subset of them.

We want the equivalent of:

buffer[0] = GPIO1_DR;
buffer[1] = GPIO1_DR;
buffer[2] = GPIO1_DR;
buffer[3] = GPIO1_DR;
// ...

except each assignment happens when a hardware trigger arrives.

That tells us most of the DMA configuration immediately.

The source address always stays the same:

Source = GPIO1_DR
Source offset = 0

The destination moves forward one 32-bit word after each transfer:

Destination = buffer
Destination offset = 4 bytes

And because the GPIO registers require 32-bit access, each transfer is 4 bytes.

Using DMAChannel, much of that setup can be expressed quite simply:

DMAChannel dma;

dma.begin();
dma.source(GPIO1_DR);
dma.destinationBuffer(dmaBuffer, sizeof(dmaBuffer));

That's a much friendlier starting point than manually programming every TCD field.

DMAChannel also dynamically allocates a DMA channel. That's useful because Teensy libraries which use DMA generally use the same mechanism, reducing the chance that two libraries accidentally try to own the same hardware DMA channel.

Minor Loops and Major Loops

There are two DMA terms worth understanding because you'll encounter them constantly in the reference manual: minor loop and major loop.

For our GPIO capture, think of one minor loop as one sample.

A hardware event occurs:

clock edge
    |
    v
DMA request
    |
    v
read GPIO1_DR
    |
    v
write one uint32_t

Then the destination pointer advances four bytes.

The major loop is the collection of all those individual transfers needed to fill the buffer.

For example, with:

#define DMABUFFER_SIZE 4096

uint32_t dmaBuffer[DMABUFFER_SIZE];

we can configure DMA to perform 4096 minor transfers.

When that major loop completes, DMA can generate an interrupt.

dma.interruptAtCompletion();
dma.attachInterrupt(dmaInterrupt);

Now instead of interrupting the CPU for every sample, we interrupt it once after thousands of samples.

That's the real payoff.

The Harder Part: Where Does the DMA Request Come From?

Moving data from GPIO into RAM isn't actually the most difficult part.

Generating exactly one DMA request per sample is where things become interesting.

If we have an external ADC clock, we'd like every rising or falling edge of that clock to cause one DMA transfer.

But GPIO itself isn't one of the normal DMA request sources.

This is where the i.MX RT crossbar—XBAR—becomes useful.

XBAR is essentially a programmable routing fabric inside the chip. Signals from different peripherals and I/O pins can be connected to other internal peripherals.

For an external sampling clock, we can build this route:

External clock pin
       |
       v
     IOMUX
       |
       v
      XBAR
       |
       v
 DMA request generator
       |
       v
     DMAMUX
       |
       v
      DMA

It looks complicated because it is several separate peripherals, but each block is doing one fairly simple job.

Routing an External Clock Through XBAR

Suppose Teensy pin 4 carries our external sampling clock.

That pin can be routed to an XBAR input.

First we configure the pin's mux:

IOMUXC_SW_MUX_CTL_PAD_GPIO_EMC_06 = 3;

Then make sure that XBAR signal is configured as an input:

IOMUXC_GPR_GPR6 &=
    ~(IOMUXC_GPR_GPR6_IOMUXC_XBAR_DIR_SEL_8);

There's also a daisy-chain selection because this XBAR input can come from more than one physical pad:

IOMUXC_XBAR1_IN08_SELECT_INPUT = 0;

Then connect that XBAR input to one of the DMA request outputs:

xbar_connect(
    XBARA1_IN_IOMUX_XBAR_INOUT08,
    XBARA1_OUT_DMA_CH_MUX_REQ30
);

We also need to configure the XBAR output to generate a DMA request on the edge we care about.

For a rising edge:

XBARA1_CTRL0 =
    XBARA_CTRL_STS0 |
    XBARA_CTRL_EDGE0(1) |
    XBARA_CTRL_DEN0;

Finally, tell our DMA channel which hardware event to use:

dma.triggerAtHardwareEvent(DMAMUX_SOURCE_XBAR1_0);

Now every selected clock edge can cause one GPIO sample to be transferred into RAM.

There is one more easily missed detail.

The XBAR peripheral needs its clock enabled:

CCM_CCGR2 |= CCM_CCGR2_XBAR1(CCM_CCGR_ON);

Do this before configuring XBAR.

Otherwise you can write perfectly reasonable-looking XBAR configuration code and spend a lot of time wondering why none of it works.

Why Not Trigger Directly From a Timer?

If the sampling clock is generated internally rather than externally, using a timer sounds like the obvious solution.

There's an important catch.

A timer can assert a DMA request, but depending on how the timer and DMA are configured, the timer may not receive the acknowledgement it needs when DMA services that request. The request can remain asserted.

DMA then sees what amounts to:

REQUEST REQUEST REQUEST REQUEST REQUEST...

instead of:

request
   |
wait for next timer event
   |
request

The result can be a DMA channel that runs continuously and transfers the entire buffer as fast as the hardware allows.

This acknowledgement behavior is one of the important pieces that's very difficult to understand from NXP's documentation alone.

Routing the timer pulse through one of XBAR's DMA request generators is usually a much cleaner solution because those request generators automatically acknowledge the DMA service.

There is another solution involving two DMA channels: one performs the real transfer, and another performs a dummy operation that acknowledges or clears the timer condition. The first DMA channel can trigger the second.

That works, but it consumes another DMA channel and is more complicated.

Unless there's a good reason to do otherwise, I'd start with XBAR.

A Minimal GPIO-to-Memory Setup

Stripped down to the important pieces, the configuration looks approximately like this:

#include <DMAChannel.h>

DMAChannel dma;

#define BUFFER_SIZE 4096
uint32_t dmaBuffer[BUFFER_SIZE];

void dmaInterrupt()
{
    dma.clearInterrupt();
    asm("DSB");

    // Tell the main program a buffer is ready.
}

void setup()
{
    // GPIO1 bits used for parallel input
    GPIO1_GDIR &= ~(0x03FC0000u);

    // Move these pins from fast GPIO6 to DMA-accessible GPIO1
    IOMUXC_GPR_GPR26 &= ~(0x03FC0000u);

    // DMA: GPIO -> memory
    dma.begin();
    dma.source(GPIO1_DR);
    dma.destinationBuffer(dmaBuffer, sizeof(dmaBuffer));

    dma.interruptAtCompletion();
    dma.attachInterrupt(dmaInterrupt);

    // Enable XBAR
    CCM_CCGR2 |= CCM_CCGR2_XBAR1(CCM_CCGR_ON);

    // Route Teensy pin 4 into XBAR
    IOMUXC_SW_MUX_CTL_PAD_GPIO_EMC_06 = 3;

    IOMUXC_GPR_GPR6 &=
        ~(IOMUXC_GPR_GPR6_IOMUXC_XBAR_DIR_SEL_8);

    IOMUXC_XBAR1_IN08_SELECT_INPUT = 0;

    // Rising edge generates DMA request
    XBARA1_CTRL0 =
        XBARA_CTRL_STS0 |
        XBARA_CTRL_EDGE0(1) |
        XBARA_CTRL_DEN0;

    xbar_connect(
        XBARA1_IN_IOMUX_XBAR_INOUT08,
        XBARA1_OUT_DMA_CH_MUX_REQ30
    );

    dma.triggerAtHardwareEvent(DMAMUX_SOURCE_XBAR1_0);

    dma.enable();
}

This isn't meant as a universal copy-and-paste DMA library. The pin mapping and masks have to match the hardware you're actually using.

But it shows the basic architecture without all the complexity found in something like OctoWS2811.

Don't Start by Copying OctoWS2811's TCD

OctoWS2811 is a useful reference because it demonstrates that GPIO DMA works on Teensy 4, but I wouldn't recommend learning DMA by trying to understand its entire transfer configuration.

It's doing something substantially more complicated.

OctoWS2811 generates waveform data dynamically in chunks and uses multiple DMA operations. Its TCD configuration takes advantage of capabilities that simply aren't necessary for straightforward data acquisition.

For continuous input, a better mental model is the Teensy Audio library.

The audio code commonly lets DMA run continuously through a buffer. An interrupt occurs when part of the buffer has been filled, software consumes that part, and DMA continues filling another part.

Conceptually:

DMA ---> [ HALF A | HALF B ]
           ^          ^
           |          |
        process     filling

Then:

DMA ---> [ HALF A | HALF B ]
           ^          ^
           |          |
        filling     process

That's often exactly what we want for an ADC or parallel digital acquisition system.

Configure the DMA once, let it run continuously, and respond only when enough data has accumulated to justify involving the CPU.

Circular Buffers Make This Much Easier

For continuous acquisition, the destination address can automatically wrap back to the beginning of the buffer after reaching the end.

At the raw TCD level, the important setting is the final destination adjustment—often discussed as DLAST.

The DMA increments the destination by four bytes after each GPIO sample:

buffer + 0
buffer + 4
buffer + 8
buffer + 12
...

When the major loop finishes, DLAST adjusts the destination pointer back to the beginning.

Then DMA can simply continue.

That means we don't have to stop the acquisition, manually reset the pointer, and restart everything for every buffer.

DMAChannel provides helpers for common configurations, and I'd use those whenever possible rather than manually filling in every TCD register.

Don't Forget the Interrupt Cleanup

A typical DMA interrupt handler should clear the DMA interrupt:

void dmaInterrupt()
{
    dma.clearInterrupt();
    asm("DSB");

    bufferReady = true;
}

The DSB—Data Synchronization Barrier—is important on Cortex-M7 because writes to peripheral registers can be buffered.

Without the barrier, it's possible for the processor to logically leave the ISR before the peripheral write clearing the interrupt has fully taken effect.

That's the kind of tiny detail that can produce extremely confusing behavior in otherwise correct-looking code.

DMA and Cache Coherency

There's another issue that becomes important depending on where the buffer lives.

A simple global array such as:

uint32_t dmaBuffer[4096];

normally lives in Teensy's RAM1/TCM region, which isn't cached in the same way as RAM2.

But consider:

DMAMEM uint32_t dmaBuffer[4096];

or memory allocated with malloc(). Those normally reside in RAM2. External PSRAM on Teensy 4.1 is also cached.

DMA doesn't know anything about the Cortex-M7 cache.

DMA reads and writes physical memory. The CPU may be reading or writing cached copies of that memory.

That can produce a nasty situation:

CPU sees:       old cached data
DMA wrote:      new physical data

Both pieces of hardware are behaving correctly. They're simply looking at different copies.

Teensy provides cache maintenance functions for dealing with this.

Before DMA sends data from memory to a peripheral, flush modified CPU cache contents to physical memory:

arm_dcache_flush(buffer, size);

For DMA writing from a peripheral into memory, invalidate the relevant cache so the CPU subsequently reloads the DMA-written data:

arm_dcache_delete(buffer, size);

There's also:

arm_dcache_flush_delete(buffer, size);

The exact operation depends on which direction the data is moving.

DMA buffers in cached memory should also generally be aligned appropriately. You'll often see code like:

DMAMEM uint32_t dmaBuffer[4096]
    __attribute__((aligned(32)));

Thirty-two-byte alignment matches the Cortex-M7 cache-line size and avoids several unnecessary headaches.

How Fast Can GPIO DMA Actually Go?

This is where it's important not to confuse the 600 MHz ARM clock with the speed of every peripheral inside the chip.

The normal GPIO registers used by DMA are on the peripheral side of the device. They aren't equivalent to the fast GPIO6 access the CPU gets.

Experiments in the forum showed the difference quite clearly.

Direct CPU polling from GPIO6 can be considerably faster than equivalent access through GPIO1. Tests with heavily unrolled loops reached roughly 66 million GPIO6 reads per second at a 600 MHz CPU clock, while comparable GPIO1 testing was around 21 million reads per second.

Those numbers aren't specifications for DMA throughput, but they demonstrate an important architectural limitation: the DMA-accessible GPIO path is slower than the CPU's fast GPIO path.

Another GPIO DMA experiment using an externally clocked counter reported reliable operation around 10 MHz, with missed samples appearing above that point in that particular setup.

I wouldn't treat 10 MHz as a universal hard limit. Wiring, signal integrity, DMA contention, peripheral clocks, and the exact transfer configuration all matter.

But I also wouldn't assume that a 600 MHz processor means GPIO DMA can sample at anything remotely approaching 600 MHz.

For the original 2 MHz application, we're in much friendlier territory.

For something like a 50 MHz parallel ADC, I'd start thinking seriously about whether GPIO DMA is the right interface at all. An external FIFO, FlexIO, or another hardware interface designed for synchronous parallel data may be a better architecture.

Be Careful Trying to "Fix" This by Overclocking the Peripheral Bus

One experiment in the thread increased the peripheral/IPG clock by changing its divider and observed GPIO DMA approaching 20 MHz.

That's interesting as an experiment, but I wouldn't recommend treating it as the normal solution.

The IPG peripheral clock is intended to operate within its specified limits. Raising it beyond those limits can make peripherals unreliable, and changing the clock divider can also break software which assumes Teensy's normal F_BUS_ACTUAL configuration.

If an application only works by pushing the peripheral bus substantially beyond specification, that's a good sign to reconsider the architecture rather than depend on the overclock.

The Practical Architecture for a 2 MHz ADC

Going back to the original problem, we already have a 2 MHz clock driving the external ADC.

That's actually convenient.

Instead of generating another timer, I'd use that external sampling clock as the DMA request source.

The architecture becomes:

                +----------------+
2 MHz ADC clock | Teensy clock pin|
--------------->|     IOMUX      |
                +-------+--------+
                        |
                        v
                      XBAR
                        |
                        v
                     DMAMUX
                        |
                        v
Parallel ADC -------> GPIO1
data                    |
                        v
                       DMA
                        |
                        v
               +-----------------+
               | acquisition RAM |
               +-----------------+
                        |
                 buffer interrupt
                        |
                        v
                       CPU
                        |
                        v
                  UDP / Ethernet

This separates two jobs that were previously competing with each other.

DMA handles the time-critical acquisition.

The CPU handles networking.

That's exactly the sort of separation DMA is intended to provide.

Double Buffering

For streaming data, I'd usually arrange things so the CPU never processes memory that DMA is currently modifying.

That can be done with two buffers:

DMA -> Buffer A
CPU -> Buffer B

then

DMA -> Buffer B
CPU -> Buffer A

or with one circular buffer where interrupts occur at half and full completion.

The important rule is the same:

DMA owns one region while the CPU owns another.

That eliminates the race which can happen when networking code is reading data while an interrupt or DMA transfer is simultaneously changing it.

For the original UDP application, this is a much better model than trying to disable interrupts around:

Udp.beginPacket(...);
Udp.write(...);
Udp.endPacket();

Networking is allowed to take however long it needs, provided it finishes processing one buffer before DMA comes around and needs that memory again.

If it doesn't, then we have a throughput problem rather than an interrupt-latency problem—and that's a much easier problem to reason about.

DMA Doesn't Have to Be Mysterious

The i.MX RT1062 DMA controller has a huge number of capabilities. You can chain channels, scatter and gather, modify addresses, trigger other DMA operations, generate interrupts partway through buffers, and construct some very elaborate hardware pipelines.

You don't need any of that to get started.

For GPIO acquisition, keep the model simple:

1. Put the pins on DMA-accessible GPIO1-4.

2. Configure DMA:
      source      = GPIO register
      destination = RAM buffer
      source step = 0
      destination step = 4 bytes

3. Route a sampling event through XBAR.

4. Use that event as the DMA request.

5. Let DMA fill the buffer.

6. Interrupt the CPU only when useful amounts
   of data are ready.

Once that works slowly, increase the sample rate.

Once a single buffer works, make it circular or double-buffered.

Only after that should you start worrying about more elaborate TCD configurations.

That's generally how I approach this hardware. Don't begin by trying to understand every register in a 3,000-page reference manual. Find the smallest hardware path that accomplishes the job, get each piece working, and then add complexity only when the application actually needs it.

DMA on Teensy 4 isn't especially friendly when you're staring at the registers for the first time. But once you reduce it to event → request → transfer → buffer, the architecture starts to make a lot more sense.


Suggested Diagrams for the Published Version

Diagram 1: GPIO DMA acquisition path
External ADC Clock → IOMUX → XBAR → DMAMUX → DMA, with Parallel ADC Data → GPIO1 → DMA → RAM joining the same DMA block.

Diagram 2: Interrupt-driven versus DMA-driven sampling
Compare invoking the Cortex-M7 for every sample against DMA collecting an entire block of samples before interrupting the processor.

Diagram 3: GPIO1 versus GPIO6
Show the same physical pins switchable between fast CPU-accessible GPIO6 and slower DMA-accessible GPIO1.

Footnote

This article is based on the PJRC forum thread Teensy 4.1 How to start using DMA? and the discussion that followed between forum members.

comments | comment feed
Doctor Doom Shows Up to Support Seattle’s Surveillance Network

The supervillain offered a timely reminder that Flock isn't the only company doing the eye-in-the-sky dirty work.

20-Channel IC Delivers Data Center Thermal Measurement and Leak Sensing

The ADT7604 from Analog Devices measures RTDs and thermistors, as well as copper-trace resistors and resistive-based leak sensors.

The New ‘Avatar: Seven Havens’ Trailer Just Made Life Harder for Korra Defenders

The upcoming 'Avatar: The Last Airbender' sequel series from creators Michael Dante DiMartino and Bryan Konietzk premieres October 9 on Paramount+.

That ‘Impossible’ Black Hole Merger May Have Just Been a Cosmic Optical Illusion

A record-breaking black hole merger threatened to pull apart astrophysics models—but what if it was just gravity messing with us?

Snap-Fit Pi Zero 2 + Pi Cam Module 3 Case #3DThursday #3DPrinting


Remixed by wesyarber shares:

The V2 snap-fit case for the Raspberry Pi Zero 2 + Camera Module 3. Encloses both the Pi and camera in a single tidy package. Updated design with improvements over V1. Perfect for compact camera-enabled Pi projects — surveillance, timelapse, print monitoring

download the files on: https://makerworld.com/en/models/842648-v2-snap-fit-rasp-pi-zero-2-pi-cam-module-3


649-1
Every Thursday is #3dthursday here at Adafruit! The DIY 3D printing community has passion and dedication for making solid objects from digital models. Recently, we have noticed electronics projects integrated with 3D printed enclosures, brackets, and sculptures, so each Thursday we celebrate and highlight these bold pioneers!

Have you considered building a 3D project around an Arduino or other microcontroller? How about printing a bracket to mount your Raspberry Pi to the back of your HD monitor? And don’t forget the countless LED projects that are possible when you are modeling your projects in 3D!

LIVE CHAT IS HERE! http://adafru.it/discord

Adafruit on Instagram: https://www.instagram.com/adafruit

Shop for parts to build your own DIY projects http://adafru.it/3dprinting

3D Printing Projects Playlist:

3D Hangout Show Playlist:

Layer by Layer CAD Tutorials Playlist:

Timelapse Tuesday Playlist:

Connect with Noe and Pedro on Social Media:

Noe’s Twitter / Instagram: http://instagram.com/ecken

Pedro’s Twitter / Instagram: http://instagram.com/videopixil

‘Dark Matter’ Is Addressing an Obvious Plot Point in Fascinating Ways

io9 has an action-packed clip from season two’s third episode, 'Everything Beautiful, Everything Terrible.'

Custom AMOLED Wearable Makes Great Icebreaker

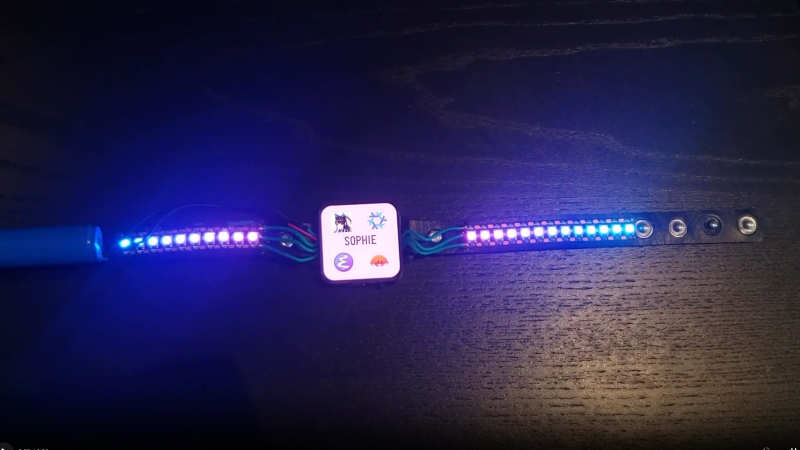
Nifty little AMOLED screens are easy to get nowadays, and [Sophie D] demonstrates they are both thin and light enough to be worn with OpenChoker, a design for a choker necklace that was a hit at DEF CON.

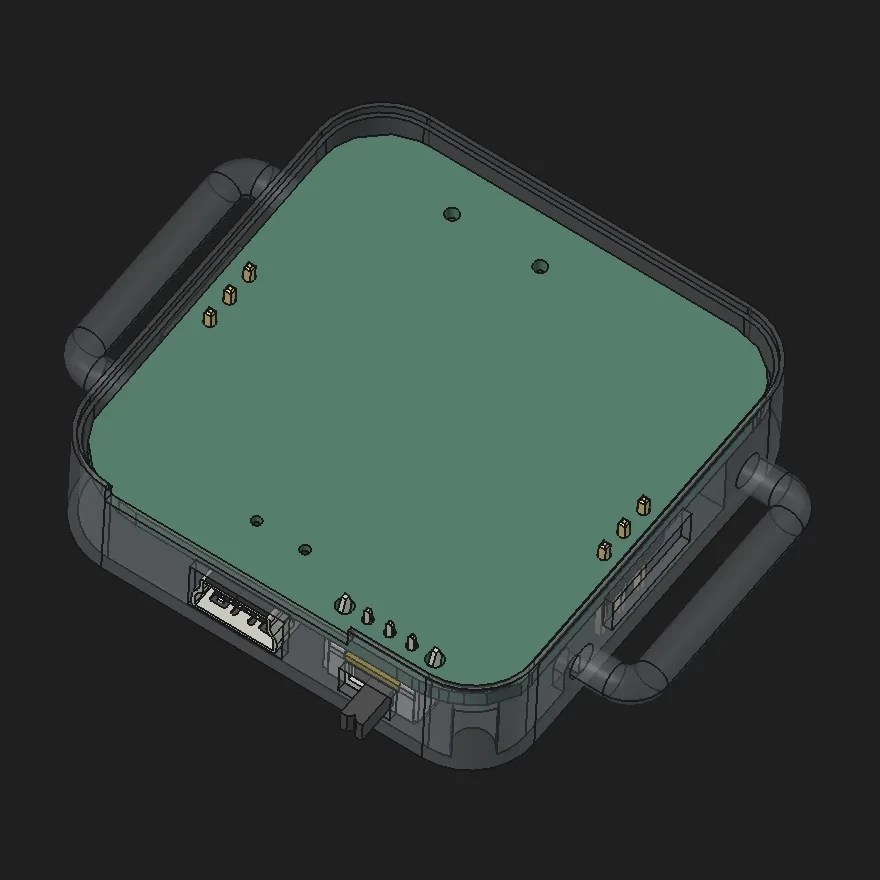
The choker consists of an AMOLED touchscreen flanked by short RGB LED strips. Behind the display is the PCB which contains an RP2350 and micro SD card slot for external storage, and at the rear of the choker is an 18650 cell to power it all. The display plays an eye-catching animation that gets generated on the fly while the LEDs sparkle away.

[Sophie] shares a number of interesting takeaways from designing and building this device. One is that the bulk of the PCB design work was interfacing to the display, since no existing footprint or reference design could be found. So if you find yourself with a Hello Lighting HL020E21-02 2.14″ touchscreen display you’re hankering to use in your own project, do yourself a favor and check out [Sophie]’s board design instead of starting from scratch.

Battery life was more than enough for a device like this. A single 18650 cell powered the choker effortlessly for a 16-hour stretch and still the cell measured a robust 3.7 V. While a light-up choker used indoors isn’t a great candidate for wearable solar power, it’s encouraging that there’s no need for a tethered battery pack.

Another tip to consider relates to the screen’s touch sensitivity. In short, the capacitive touch screen responded perfectly when plugged into a development computer, but when mounted and isolated on the choker it responded so poorly as to be useless. It didn’t keep the rest of the choker from doing its job, but it might be worth keeping in mind as something to watch out for with a device like this.

There’s one final mystery [Sophie] ran into: with only one day to spare, glue used to affix some wires ended up melting away the wire insulation, revealing bare copper. We’re not sure what happened there, but if nothing else it’s a reminder that Murphy’s Law is always ready to strike when one is on a deadline.

Tech Media News - Tech Media Aggregator
Contact delabs - Send an Email

Notes delabs: Chargers and Safety

Do not use Fast Chargers on the old Devices. Fast Chargers can go to 9V and 12V which damage older devices that are meant for only 5V. Use only the charger supplied by the device maker when possible.

Also new Power banks that have Fast Charging may damage old 5 V Devices. Use a Legacy 5V 2A power bank for older devices.

image for illustration only

Points to note

   Do not charge when it is raining or when mains power fluctuates.
   Do not use device when you are charging, HV zap can kill on fail.
   Charge devices when you are around and awake, fire hazard.

Read more

delabs News: Stanford Bunny Exists

Stanford Bunny the God of 3d Printing still Exists. The Stanford 3D Scanning Repository. 

Read more

TMN Updates: About

Engineers, Technologists, Manufacturers, Firms or Companies can post Sponsored Articles and Listings in our sites and blogs - delabs sections

About Tech Media Network - This very page will have updated information on delabs and dapj. Blog will contain updates and other posts. 

delabs tech

Electronics Docs: 110 OpAmp Projects

110 OpAmp Projects

Essentially a high-gain dc amplifier, with a high input and low output impedance, the modern op-amp has a multitude of practical applications both in the home and in industry.

.

Electronics Docs: Ostermiller Basic and Scientific Calculator

Ostermiller Basic and Scientific Calculator

Scientific Expression or Formula Calculations. Twenty Transaction Memory and Tape, Different bases like Decimal and Octal, Logic Math, Functions, Constants.

.

TMN Updates: Earthing Practice and Power Quality

Earthing Practice and Power Quality

Earth leakage currents arise mainly from the EMC filters built into electronic equipment with switched mode power supplies. Standards limit the leakage current from non-fixed equipment (i.e. equipment that plugs into a standard socket outlet) to less than 3.5 mA. When a lot of electronic equipment is in use, the total leakage current in the protective conductor can become significant.

TMN Updates: Backdrop CMS

Backdrop CMS

Backdrop CMS is a Open source, community-developed, content management system, written in PHP, and licensed under the GNU General Public License. Backdrop CMS was forked from the Drupal CMS in 2013 by two Drupal developers, Nate Lampton and Jen Lampton.

TMN Updates: Handbook of Amplifiers Oscillators

Handbook of Amplifiers Oscillators

The Complete Handbook of Amplifiers, Oscillators & Multivibrators. Basic Semiconductor Theory, Basic Transistor Theory, Amplification Frequency Response of Transistors, Amplifier Basics, Designing Transistor Amplifiers, Field-Effect Transistors, Designing with FETs, Bipolar Transistor Power Amplifiers.

Electronics Circuits: Two Op-Amp Differential Amplifier

Two Op-Amp Differential Amplifier

The Input Impedance of this module is very high and is symmetric. This circuit can be used for strain gauges and for four wire measurements.

.

Electronics Docs: The 8051 89C52 80C31 Page

The 8051 89C52 80C31 Page

Build your own a programmer for writing intel-HEX file to the 89C51, 89C52 and 89C55, PCB file included. The prototype board may be builtusing universal PCB with point-to-point soldering.

.

delabs News - delabs and dapj blogs.

delabs Technologies

Interface with delabs

delabs sections - This Sitemap of all delabs and dapj.

Message, Post or Send Email at delabs desk. 

Please Donate to delabs to help us Improve our Services.

Membership Sections are marked like - Website.M


Members Section

Technology Blogs


Industrial Circuit Design HTML Circuit Archive of delabs 25 Yr old in 2025. delabs designs from 80s, 90s...


dapj tech - Electronic Engineering and Design. - Being Rebuilt with more current Technologies. (Most sub-domains are deleted, the pages are available for Members).

Parts of content moved to Sections that are only for Members -  Ideas of delabs – Technical Memoirs of delabs. Industrial Companies – Industrial and Manufacturing Firms and Companies.


Some Domains, Sections, Blogs and services have been moved to members area. Some are reorganized to reduce costs and to upgrade to the newer technologies.


Status - Current as of 03/11/2025


Web Archive Record 2020 - Anwheel.com and EEMetric,com are being closed. (cost cutting)


Sub-Sections Search dapj tech - Started in 2025, Anybody can Suggest a Tech Resource or go for a Paid Search Listing. Listing also done in Directory Sections below.

Tech Directory sections EE Resources DC and a mirror at EE Resources EC

Search and Find Tech Things - This search includes non-technical websites. Promote anything in the web Paid Search Listing.


Desktop

Advertising in delabs

The Sponsor Firm will get a Banner or Ad-Slot at the Top of the Blog, this will help brand building. Promote a product or service of the company. See the complete list of delabs blogs and sites at the Bottom of this page. delabs, dapj, Anwheel and EEMetric are brands of delabs Technologies. Electronic Companies or Engineering Firms can sponsor a Blog from delabs for an Entire Year. delabs can help start your website or blog. This service is for Engineering and Electronics Companies.

on: 12/15/2019

Privacy and Security

delabs Sites does not collect or ask the visitor to provide any personal or private information. delabs Sites does not use any technical or other mechanisms to obtain your name, email, phone, address or any other personal information. delabs understands the importance of user privacy and will ensure that private information is not collected by the web pages or software at delabs Sites.

on: 12/12/2019

Contact delabs directly

Request a Product Design Service or Advertise in delabs by contacting delabs Technologies. delabs can give you technology ideas,. ask technical or DIY Questions too. Sponsor or Advertise in delabs Sites or Blogs related to Electronics - Advertise in delabs. Electronic Design Service Requests, EE Tech Questions, Hobby DIY Doubts - Tech EE Service. There is a Simple Contact delabs Form to send me a short message.

on: 8/19/2019